SELECTED PUBLICATIONS & PREPRINTS
Research
My research connects preference-based reinforcement learning, multimodal robot-data quality, vision-language-action models, and physical deployment. The common question is how robots can learn from imperfect human-provided data while preserving the behavioral distinctions that matter in the real world.
Complete citation history is available on Google Scholar. * Equal contribution.
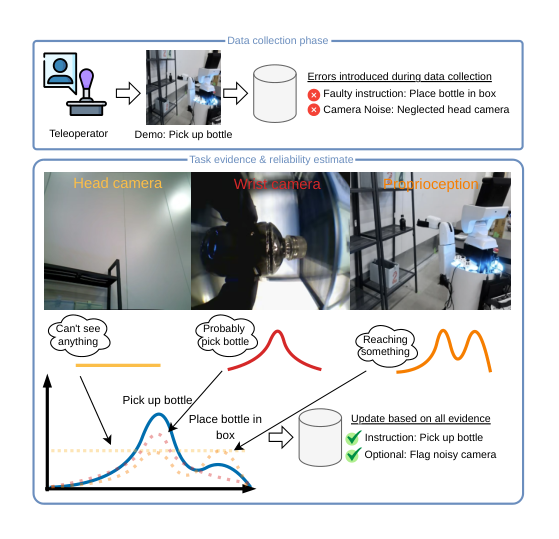
Auditing Instruction–Trajectory Mismatches in Multimodal Robot Demonstrations
We study demonstrations that execute plausible behavior but are paired with the wrong language instruction. Multimodal Probabilistic Fusion is a training-free auditing method that combines vision and proprioceptive evidence to detect and relabel these mismatches before VLA training.
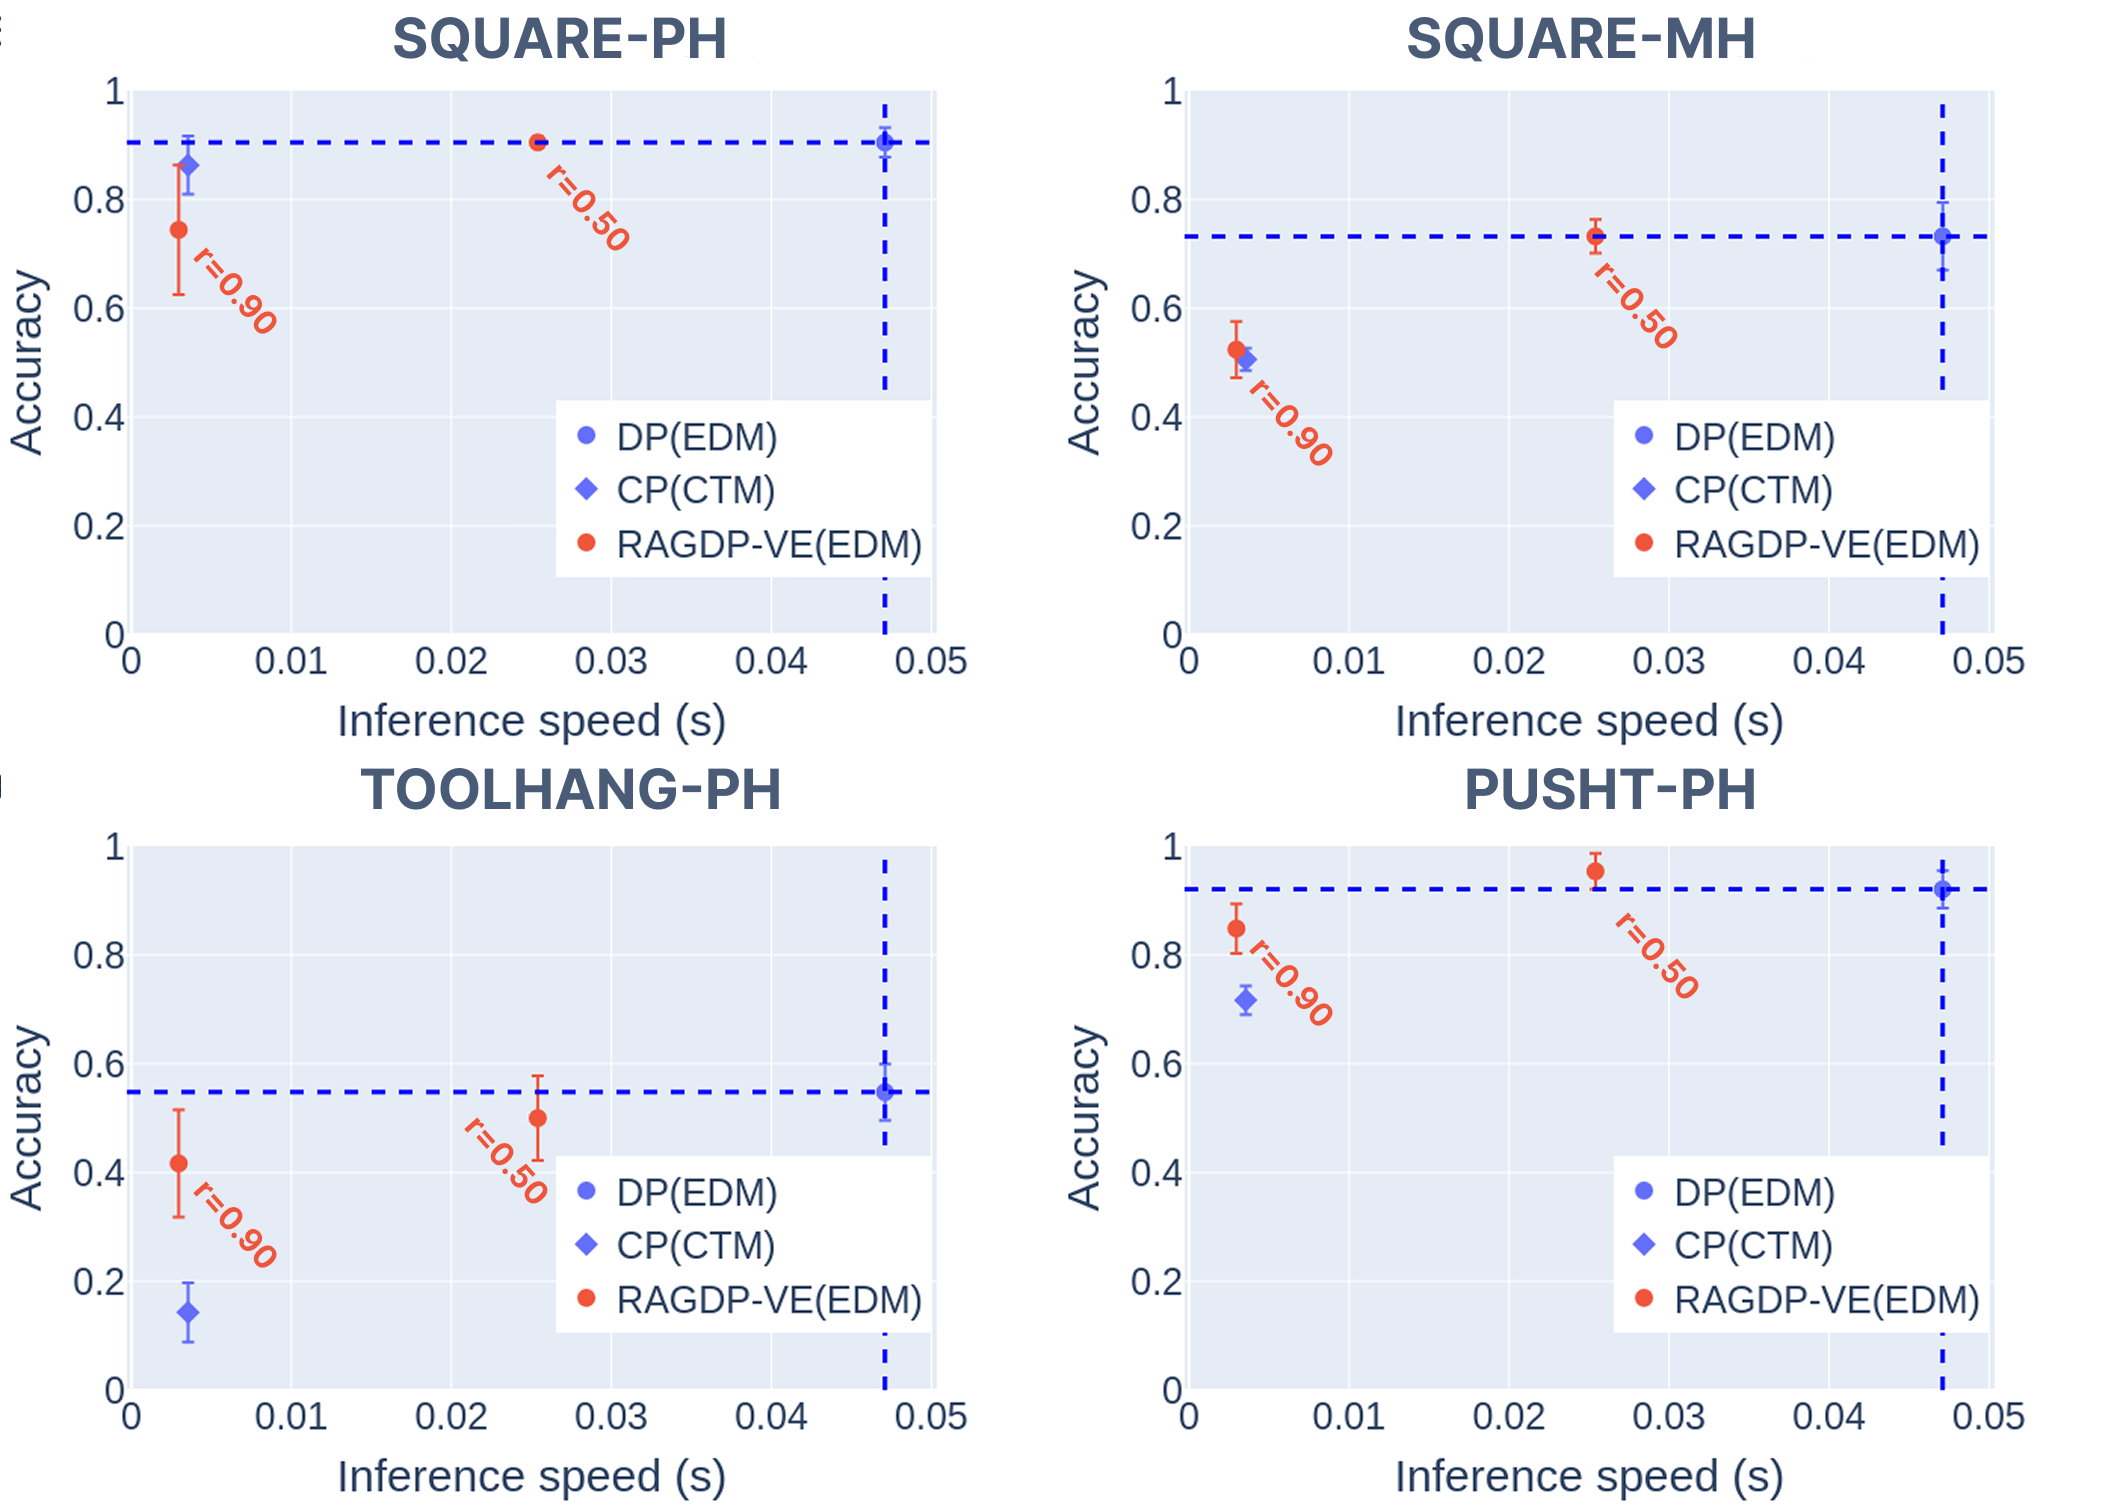
Retrieve-Augmented Generation for Speeding up Diffusion Policy without Additional Training
RAGDP retrieves relevant expert actions and injects them into an intermediate denoising step, improving the speed–accuracy trade-off of pretrained diffusion policies without distillation or additional model training.
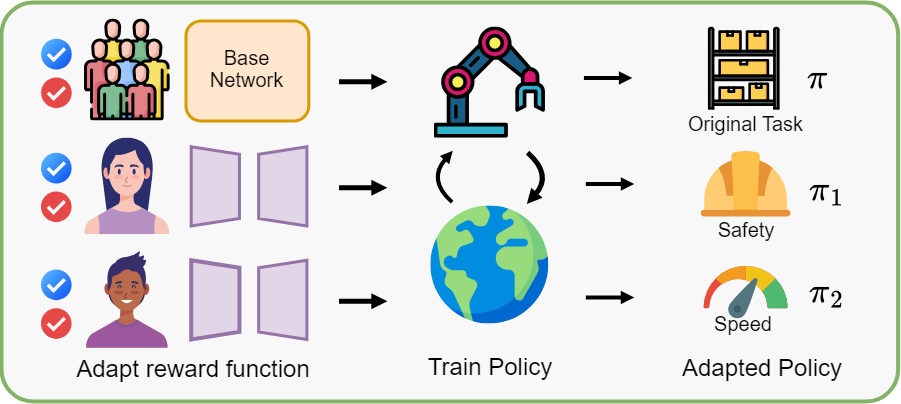
FLoRA: Sample-Efficient Preference-based RL via Low-Rank Style Adaptation of Reward Functions
FLoRA adapts pretrained robot behavior to individual preferences through low-rank style parameters in the reward function, reducing the amount of new feedback needed while retaining the original task behavior.
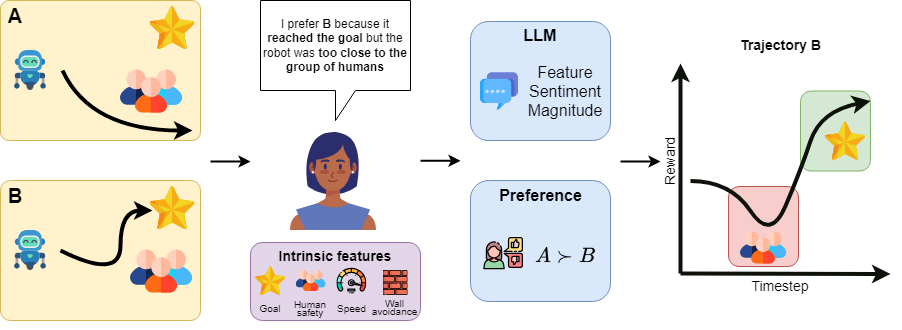
PREDILECT: Preferences Delineated with Zero-Shot Language-based Reasoning in Reinforcement Learning
PREDILECT uses zero-shot language reasoning to extract more granular information from optional natural-language explanations accompanying pairwise preferences, improving how reward models represent what a person actually wants.
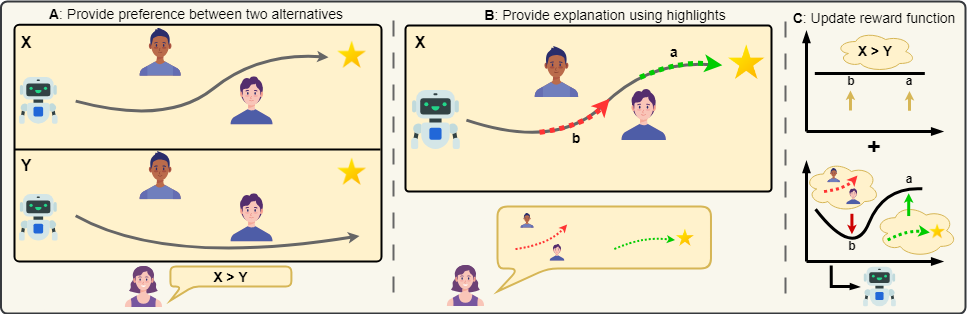
POLITE: Preferences Combined with Highlights in Reinforcement Learning
POLITE supplements trajectory preferences with positive and negative temporal highlights so a reward model can assign credit to the behavior that actually caused the judgment. The paper was nominated for three ICRA best-paper awards.
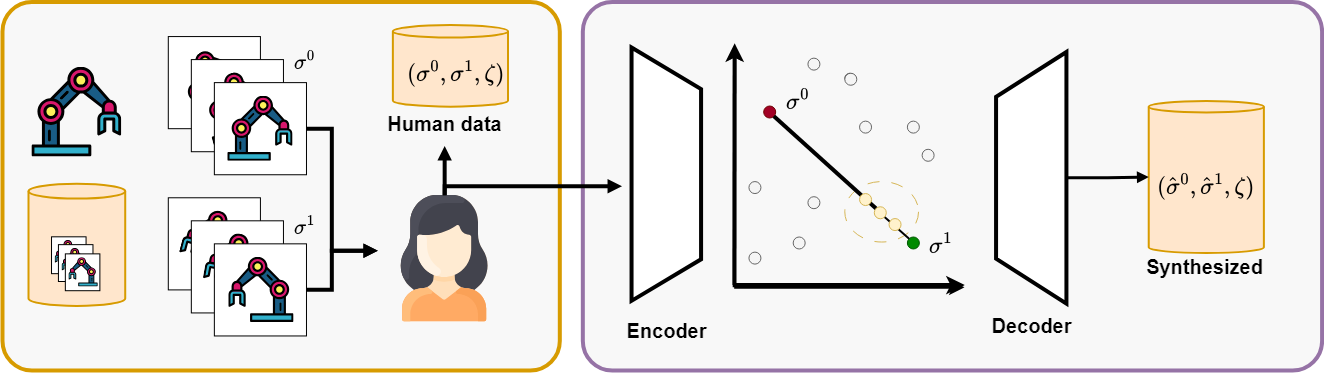
SEQUEL: Semi-Supervised Preference-based RL with Query Synthesis via Latent Interpolation
SEQUEL learns a latent representation of trajectory pairs and synthesizes additional preference queries through interpolation, using semi-supervised learning to extract more value from limited human feedback.